World-Consistent Character Video Generation
with Large-Angle Camera Control
1Electronic Information School, Wuhan University 2MiLM Plus, Xiaomi Inc. 3School of Robotics, Wuhan University
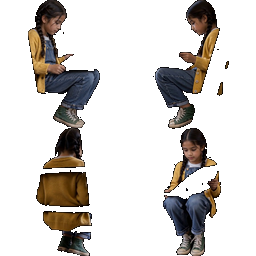
one frame & anchors from any viewpoint · any large-angle move · identity intact
one subject · two large-angle trajectories · rendered in a single pass
Precise camera control is essential for cinematic character video generation, yet existing methods struggle to follow large-angle trajectories while preserving character identity across viewpoint changes. We introduce CLACT, a character-centric benchmark of 80,000 training samples and 42 evaluation scenes, and WorldCast, a framework that couples scale-aligned geometric guidance with geometry-aligned multi-view character memory (GAMA). WorldCast achieves the best camera-control accuracy and character consistency while maintaining competitive visual quality.
Figure 1 · Large-angle trajectories that break prior methods — best camera accuracy (ATE ↓), cross-view consistency (MEt3R ↓), and identity preservation, at competitive image quality.
A character-centric dataset & benchmark for Large-Angle Camera Trajectories: 80,000 synthetic training samples (50K UE5 + 30K Blender), 42 synthetic and real-world evaluation scenes, accurate camera geometry, and paired multi-view character observations. Dataset · coming soon
The initial view is lifted to a colored 3D point cloud with calibrated depth scale, then splat-rendered along the target trajectory — producing trajectory-aligned RGB guidance and coverage masks that tell the model exactly what to complete.
Multi-view anchor geometry is aligned with the target trajectory in a shared coordinate frame via Umeyama alignment, enabling geometry-aware retrieval and injection of view-relevant character features into video tokens.
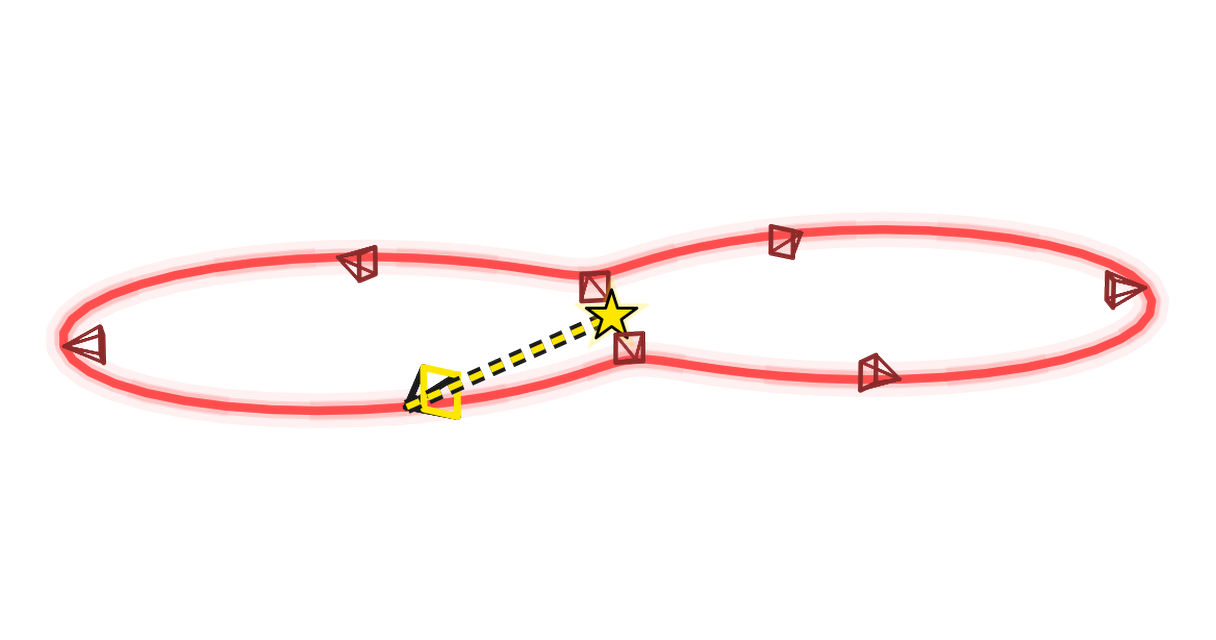
Pick a subject and a camera trajectory — orbit, tilt, push-pull, lemniscate, zoom-out. Every clip below is generated by WorldCast from the single shown input frame plus multi-view anchors.
WorldCast couples scale-aligned geometric guidance with geometry-aligned multi-view character memory, built on the Wan2.1-I2V-14B flow-matching backbone.
Figure 2 · WorldCast overview — trajectory-aligned geometric guidance coupled with geometry-aligned multi-view character memory (GAMA).
Evaluated on 42 character-centric scenes × 6 trajectories. WorldCast leads on every camera-control and character-consistency metric while keeping competitive visual quality.
| Method | Anchors | ATE ↓ | RTE ↓ | RRE ↓ | MEt3R ↓ | ArcFace ↑ | CLIP ↑ | DINO ↑ | Subj. ↑ | IQ ↑ |
|---|---|---|---|---|---|---|---|---|---|---|
| Camera-Controlled Generation | ||||||||||
| CamI2V | ✗ | 0.351 | 0.281 | 11.490 | 0.405 | 0.147 | 0.804 | 0.675 | 0.874 | 0.686 |
| DualCamCtrl | ✗ | 0.297 | 0.082 | 3.607 | 0.408 | 0.185 | 0.796 | 0.661 | 0.904 | 0.699 |
| GEN3C | ✗ | 0.130 | 0.038 | 1.255 | 0.306 | 0.433 | 0.819 | 0.696 | 0.915 | 0.716 |
| Uni3C | ✗ | 0.098 | 0.033 | 1.069 | 0.324 | 0.374 | 0.823 | 0.691 | 0.911 | 0.711 |
| Lyra 2.0 | ✗ | 0.142 | 0.034 | 1.741 | 0.316 | 0.394 | 0.817 | 0.691 | 0.916 | 0.725 |
| Novel-View Generation | ||||||||||
| ViewCrafter | ✗ | 0.353 | 0.203 | 9.198 | 0.395 | 0.223 | 0.810 | 0.683 | 0.888 | 0.715 |
| ViewCrafter ⋆ | ✓ | 0.361 | 0.196 | 8.902 | 0.419 | 0.195 | 0.795 | 0.655 | 0.869 | 0.715 |
| MVGenMaster | ✗ | 0.125 | 0.099 | 2.929 | 0.370 | 0.227 | 0.796 | 0.655 | 0.869 | 0.699 |
| MVGenMaster ⋆ | ✓ | 0.218 | 0.152 | 6.938 | 0.301 | 0.299 | 0.821 | 0.707 | 0.862 | 0.691 |
| Video Re-Rendering | ||||||||||
| ReCamMaster | ✗ | 0.295 | 0.067 | 2.600 | 0.335 | 0.363 | 0.812 | 0.678 | 0.904 | 0.689 |
| DepthDirector | ✗ | 0.289 | 0.066 | 1.732 | 0.332 | 0.423 | 0.826 | 0.686 | 0.919 | 0.705 |
| CameraAnything | ✗ | 0.244 | 0.078 | 4.879 | 0.341 | 0.358 | 0.807 | 0.648 | 0.898 | 0.700 |
| Ours | ||||||||||
| WorldCast | ✓ | 0.065 | 0.020 | 0.896 | 0.228 | 0.555 | 0.830 | 0.719 | 0.917 | 0.719 |
White = best per column · Underlined = second best · ⋆ = additional character views provided as input
Large-angle orbit with push-pull — the hardest shot in the benchmark. Same input, same trajectory, thirteen methods. Watch the character survive.


Left: input frame & multi-view anchors. Right: generated video along a large-angle trajectory.
@misc{worldcast, title = {WorldCast: World-Consistent Character Video Generation with Large-Angle Camera Control}, author = {Cao, Lei and Liu, Yu and Liao, Wenhua and Zhang, Peng and Wang, Fei and Zhang, Hao and Le, Jiajun and Zhou, Daiguo and Luan, Jian and Ma, Jiayi}, year = {2026}, eprint = {2610.33135}, archivePrefix = {arXiv}, primaryClass = {cs.CV}, url = {https://arxiv.org/abs/2610.33135} }